Project 02
Enterprise Knowledge Assistant
/ Overview
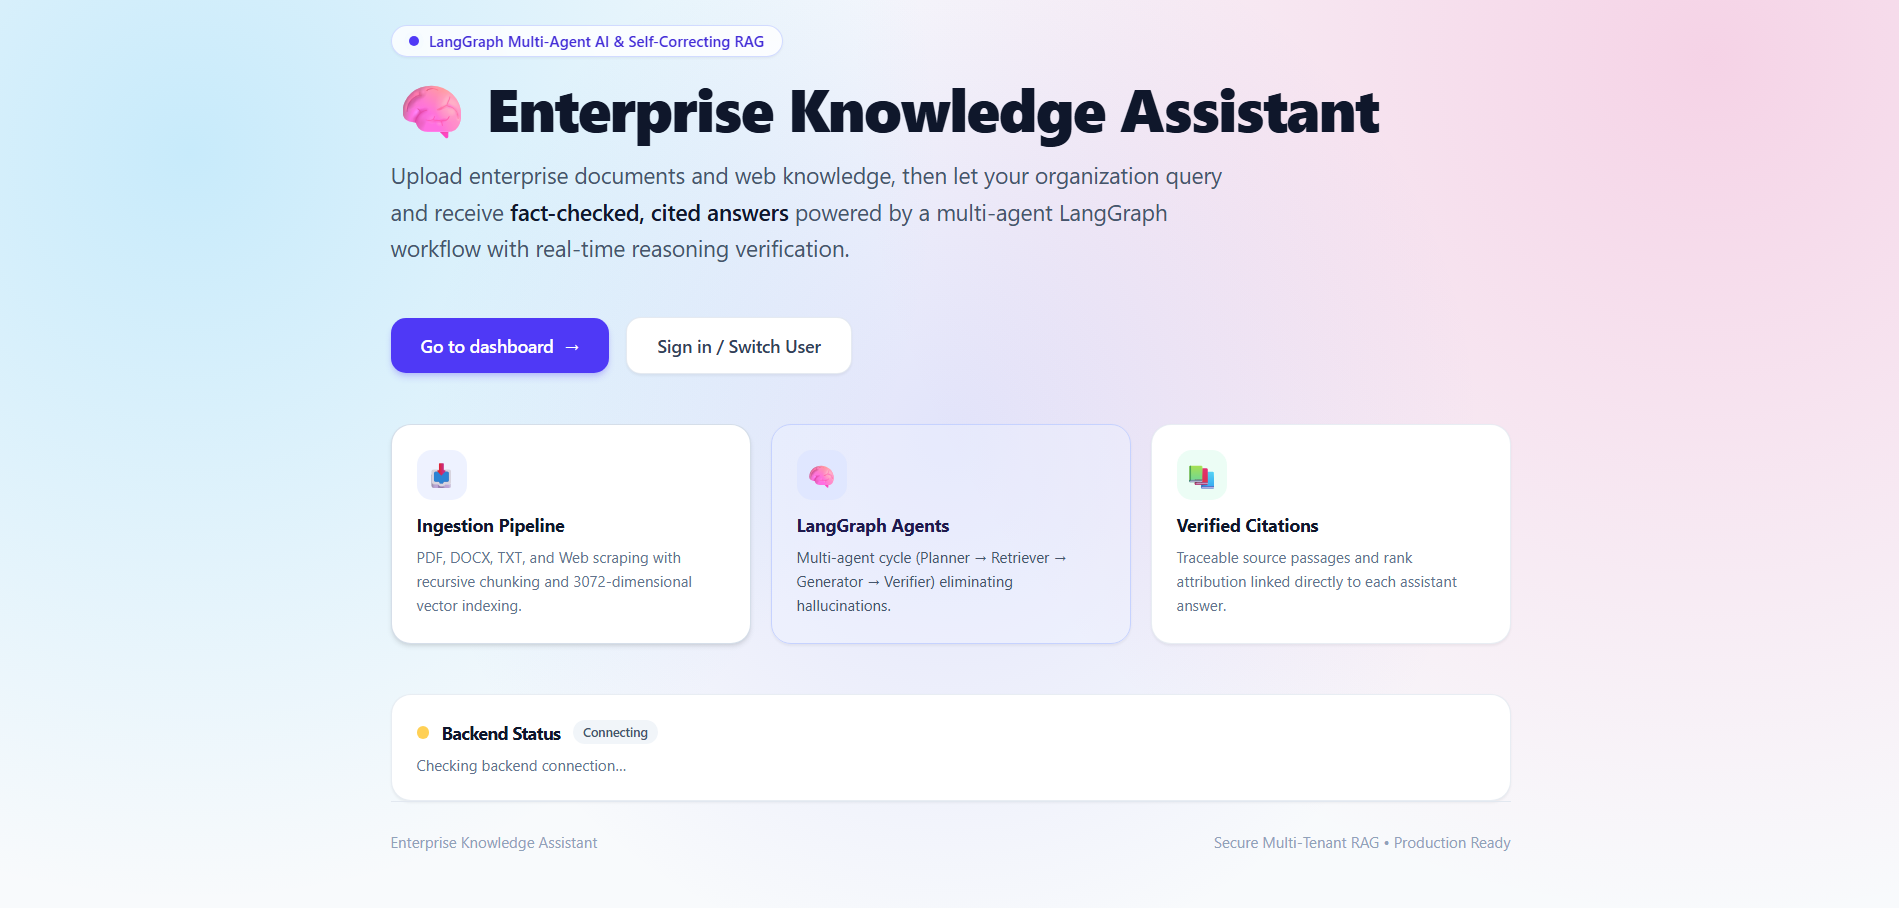
Enterprise Knowledge Assistant lets an organization ingest PDF, DOCX, and Markdown files along with crawled websites, then ask questions and get grounded answers with inline source citations that link back to the exact chunk.
It runs two decoupled loops: an asynchronous ingestion path that turns raw files into embedded, searchable chunks using Qdrant as a rebuildable index, and a latency-sensitive query path that retrieves context and runs a multi-agent pipeline (Planner, Retrieval, Verification, Generation) orchestrated by LangGraph.
/ Key Features
Ingest PDF, DOCX, and Markdown files along with crawled websites
Retrieve relevant context via Qdrant vector search and reranking
Reason with a multi-agent LangGraph pipeline: Planner, Retrieval, Verification, Generation
Answer with inline source citations linking back to the exact chunk
Per-user conversation memory, plus organizations, roles, and an admin dashboard
/ Tech Stack
Next.js 15FastAPIPythonLangGraphLangChainQdrantPostgreSQLRedisDocker
/ My Role
Architected the RAG pipeline and multi-agent orchestration, and built the ingestion and query paths along with the Next.js dashboard.